Why does this JSON validate in one tool and fail in another?
A UTF-8 BOM turns a 34-byte valid object into 37 bytes. jq passes; browser JSON.parse fails at U+FEFF. A valid stamp is a parser’s stamp.
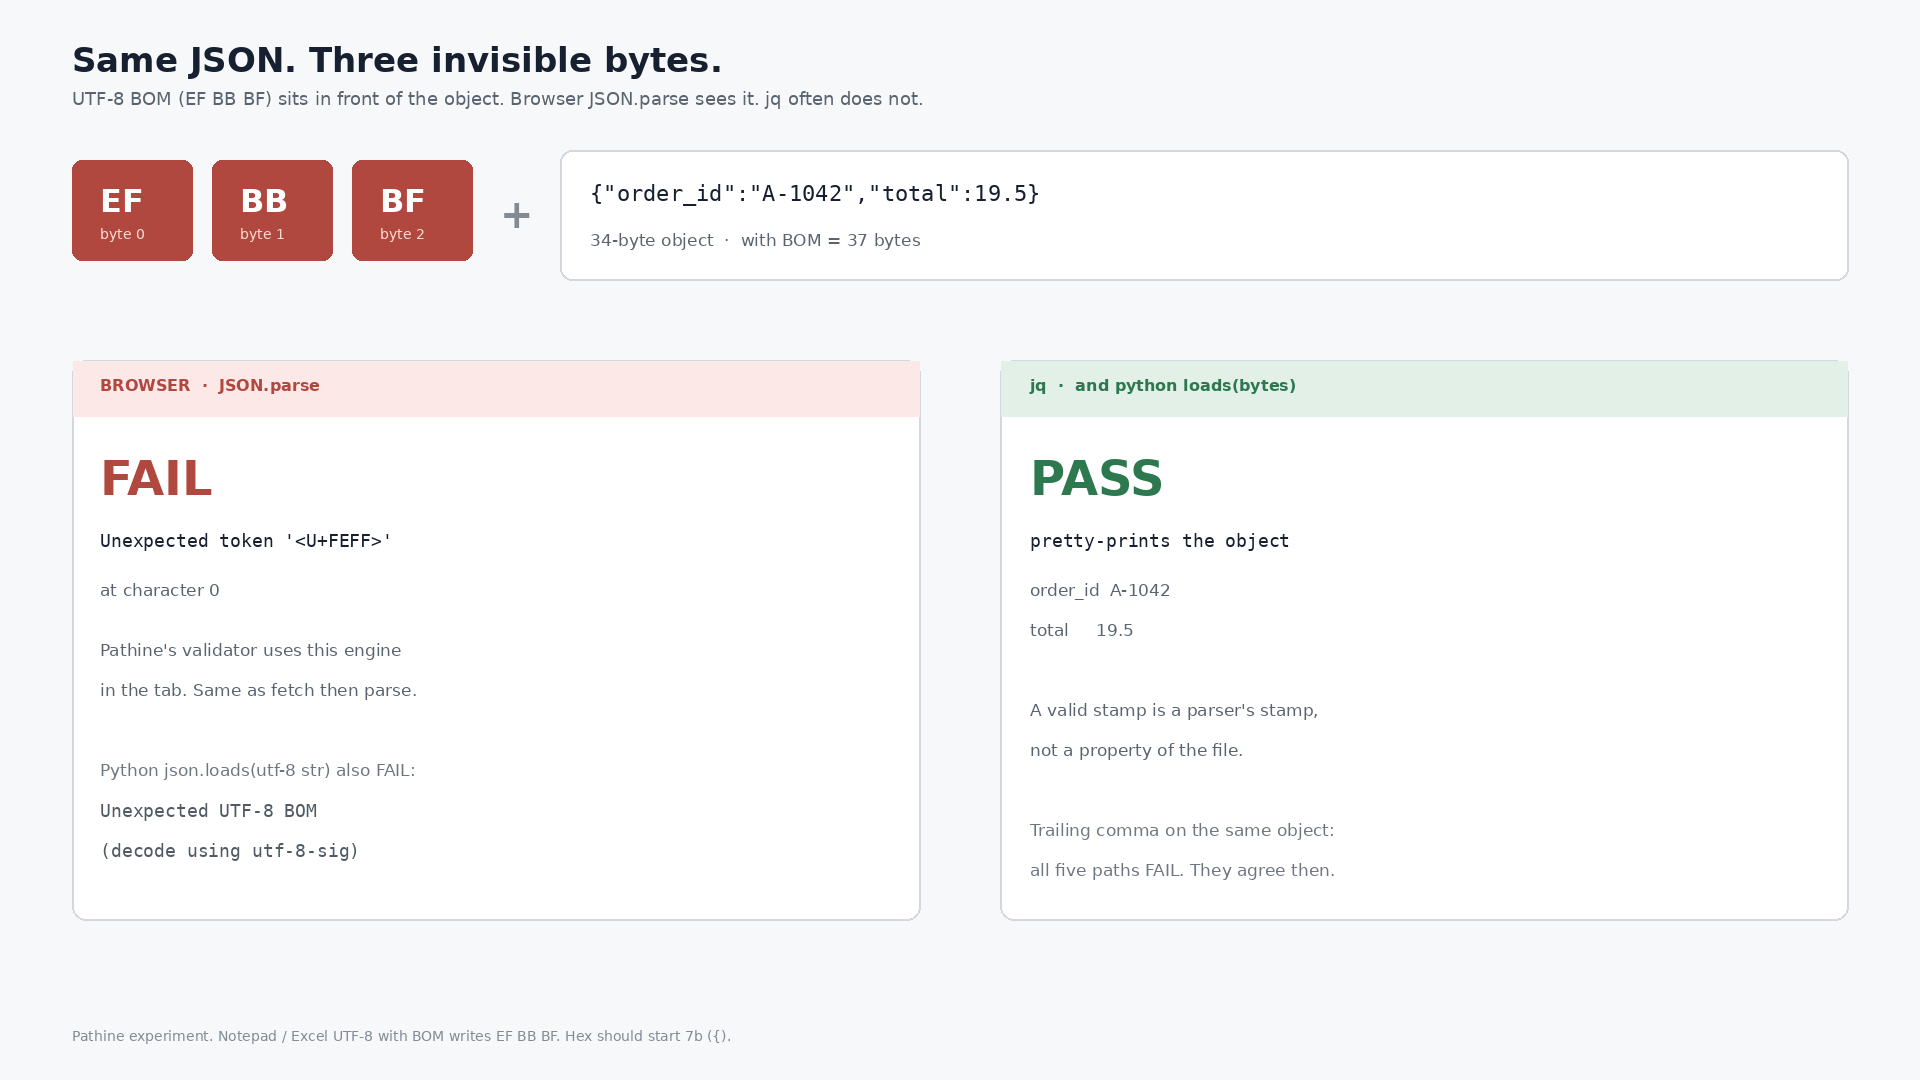
Because a “valid” stamp is a specific parser’s stamp, not a property of the file. Take a 34-byte object, {"order_id":"A-1042","total":19.5}. It passes everywhere we tried. Prefix the same bytes with a UTF-8 BOM (EF BB BF) and the file becomes 37 bytes. jq and Python json.loads on the raw bytes still say valid. Chrome / Node JSON.parse - the engine Pathine’s validator uses in the tab - says Unexpected token '<U+FEFF>' at character 0. Same file. Different door.
Measured 2026-08-31 on this computer: Python 3.13.5, Node v20.19.2, jq 1.7. We did not install json5; do not read this as a JSON5 or JSONC test.
The BOM table
The payload is always {"order_id":"A-1042","total":19.5}. The only change is three leading bytes.
| File | First bytes | Bytes | python loads(bytes) | python loads(utf-8 str) | python loads(utf-8-sig) | node JSON.parse | jq |
|---|---|---|---|---|---|---|---|
| a1042-valid.json.txt | 7b 22 6f 72… | 34 | PASS | PASS | PASS | PASS | PASS |
| a1042-utf8-bom.json.txt | EF BB BF then { | 37 | PASS → same object | FAIL | PASS | FAIL | PASS |
| a1042-trailing-comma.json.txt | 7b 22 6f 72… | 35 | FAIL | FAIL | FAIL | FAIL | FAIL |
On the BOM file, Python on the decoded UTF-8 string fails with: Unexpected UTF-8 BOM (decode using utf-8-sig): line 1 column 1 (char 0). Node fails with: Unexpected token '<U+FEFF>'. jq pretty-prints the object with no error. Do not claim “Python always accepts a BOM.” json.loads(bytes) passed; json.loads on the UTF-8 string failed on the same file. Decode with utf-8-sig and Python passes again.
Those three bytes are what Windows Notepad, Excel’s “UTF-8 with BOM,” and some other Windows saves put at the front of a text file. They are invisible in most editors. They are not invisible to JSON.parse.
The same split showed up on a longer copy (11-utf8-bom.json.txt, 256 bytes = 253 + 3): python bytes PASS, python utf-8 FAIL with the same BOM message, node FAIL on U+FEFF, jq PASS.
When JSON is actually illegal, they agree
Same object, one trailing comma (35 bytes): {"order_id":"A-1042","total":19.5,}. All five paths fail. Python: Illegal trailing comma before end of object: line 1 column 34 (char 33). Node: Expected double-quoted property name in JSON at position 34. jq: Expected another key-value pair at line 1, column 35. The trailing-comma FAQ already exists ten times over. The point here is only contrast: when the text is illegal JSON, the parsers line up. The BOM is the case they do not.
Which stamp Pathine is
Pathine’s JSON Validator runs JSON.parse in the browser tab. Paste stays on-device. Nothing uploads. The caret lands on the column the engine complains about. That is the same check a website’s fetch then JSON.parse will run - not the check jq runs on disk, and not Python’s bytes path. JSON Formatter is the tidy-output twin of that same parser, not a different engine. Neither tool does schema validation.
If your file was saved “UTF-8 with BOM” and fails in the browser but opens in jq, you are not crazy. You are holding two stamps.
A few other splits (one line each)
Two JSON values in one paste: python and node FAIL at character 56; jq PASS and prints both. NaN / Infinity: node FAIL (Unexpected token 'N'); python PASS as real NaN / +Inf; jq PASS but rewrites NaN → null and Infinity → 1.7976931348623157e+308. Integer order_id 9007199254740993: both “valid,” but python keeps 9007199254740993 and Node stores 9007199254740992. Duplicate keys: all three PASS; last wins (status=error, code=500).
A few straight answers
Why does this JSON validate in one tool and fail in another?
Different parsers. A UTF-8 BOM is the cleanest demo: jq and Python-on-bytes pass; browser JSON.parse fails at character 0.
Is the file valid or not?
Ask which parser. For a website, the browser’s answer is the one that matters.
How do I strip the BOM?
Re-save as UTF-8 without BOM, or decode with utf-8-sig before json.loads. Hex at the start should be 7b ({), not EF BB BF.